Map the official objectives.
Read the current Databricks objectives and make a short list of the areas you need to revisit before booking DB-DEP.
Revizo / Databricks / DB-DEP
DATABRICKS CERTIFICATION STUDY GUIDE
Validates advanced skills in data engineering using Databricks platform.
Download Revizo
Validates advanced skills in data engineering using Databricks platform.
Exam details are based on the available Databricks catalogue information. Confirm current requirements with the exam provider before booking.
Use the provider's current objectives as your source of truth, then organise your Revizo sessions around data and AI workflows, platform capabilities and the practical decisions named in the certification. The DB-DEP exam is listed as Multiple choice and hands-on tasks; your starting point should reflect 1+ years of Databricks experience.
Read the current Databricks objectives and make a short list of the areas you need to revisit before booking DB-DEP.
Select DB-DEP in Revizo and use focused question sessions to test one topic or decision type at a time, rather than relying on a single long cram session.
Use your results to return to incorrect answers, revisit the official material behind them and repeat short DB-DEP practice sessions until the gaps are clearer.
FREE PRACTICE PREVIEW
Review each question, its correct answer and any available source explanation before continuing your certification study in Revizo.
Answers & available explanations
QUESTION 1
An upstream system has been configured to pass the date for a given batch of data to the Databricks Jobs API as a parameter. The notebook to be scheduled will use this parameter to load data with the following code: df = spark.read.format('parquet').load(f'/mnt/source/(date)')
Which code block should be used to create the date Python variable used in the above code block?
Correct answer: E
QUESTION 2
The Databricks workspace administrator has configured interactive clusters for each of the data engineering groups. To control costs, clusters are set to terminate after 30 minutes of inactivity. Each user should be able to execute workloads against their assigned clusters at any time of the day.
Assuming users have been added to a workspace but not granted any permissions, which of the following describes the minimal permissions a user would need to start and attach to an already configured cluster.
Correct answer: D
QUESTION 3
When scheduling Structured Streaming jobs for production, which configuration automatically recovers from query failures and keeps costs low?
Correct answer: D
QUESTION 4
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert: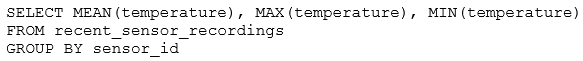
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
Correct answer: E
QUESTION 5
A junior developer complains that the code in their notebook isn't producing the correct results in the development environment. A shared screenshot reveals that while they're using a notebook versioned with Databricks Repos, they're using a personal branch that contains old logic. The desired branch named dev-2.3.9 is not available from the branch selection dropdown.
Which approach will allow this developer to review the current logic for this notebook?
Correct answer: B
QUESTION 6
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).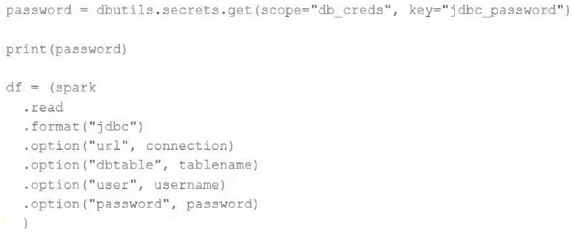
Which statement describes what will happen when the above code is executed?
Correct answer: E
QUESTION 7
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame named preds with the schema 'customer_id LONG, predictions DOUBLE, date DATE'.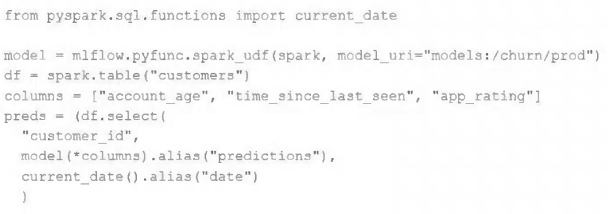
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
Correct answer: A
QUESTION 8
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable: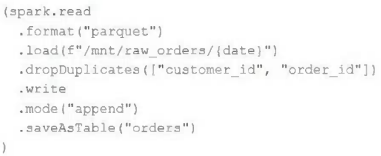
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
Correct answer: B
QUESTION 9
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.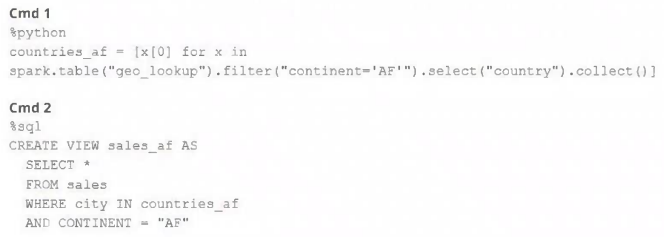
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
Correct answer: E
QUESTION 10
A Delta table of weather records is partitioned by date and has the below schema: date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter: latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
Correct answer: D
QUESTION 11
The data engineering team has configured a job to process customer requests to be forgotten (have their data deleted). All user data that needs to be deleted is stored in Delta Lake tables using default table settings.
The team has decided to process all deletions from the previous week as a batch job at 1am each Sunday. The total duration of this job is less than one hour. Every Monday at 3am, a batch job executes a series of VACUUM commands on all Delta Lake tables throughout the organization.
The compliance officer has recently learned about Delta Lake's time travel functionality. They are concerned that this might allow continued access to deleted data.
Assuming all delete logic is correctly implemented, which statement correctly addresses this concern?
Correct answer: E
QUESTION 12
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create.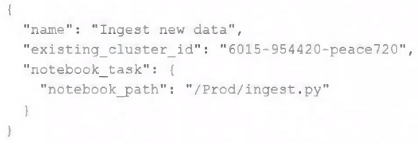
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
Correct answer: C
QUESTION 13
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the field pk_id.
For auditing purposes, the data governance team wishes to maintain a full record of all values that have ever been valid in the source system. For analytical purposes, only the most recent value for each record needs to be recorded. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
Correct answer: E
QUESTION 14
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. The user_id field represents a unique key for the data, which has the following schema: user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT
New records are all ingested into a table named account_history which maintains a full record of all data in the same schema as the source. The next table in the system is named account_current and is implemented as a Type 1 table representing the most recent value for each unique user_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the described account_current table as part of each hourly batch job?
Correct answer: C
QUESTION 15
A table in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
Correct answer: E
QUESTION 16
A table is registered with the following code: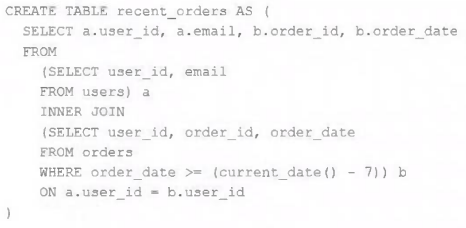
Both users and orders are Delta Lake tables. Which statement describes the results of querying recent_orders?
Correct answer: B
QUESTION 17
A production workload incrementally applies updates from an external Change Data Capture feed to a Delta Lake table as an always-on Structured Stream job. When data was initially migrated for this table, OPTIMIZE was executed and most data files were resized to 1 GB. Auto Optimize and Auto Compaction were both turned on for the streaming production job. Recent review of data files shows that most data files are under 64 MB, although each partition in the table contains at least 1 GB of data and the total table size is over 10 TB.
Which of the following likely explains these smaller file sizes?
Correct answer: A
QUESTION 18
Which statement regarding stream-static joins and static Delta tables is correct?
Correct answer: A
QUESTION 19
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
'device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT'
Code block: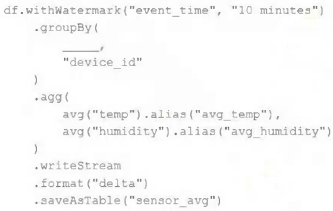
Choose the response that correctly fills in the blank within the code block to complete this task.
Correct answer: B
QUESTION 20
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below: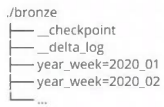
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Correct answer: E
Choose DB-DEP in Revizo and work through original, question-by-question practice on your iPhone. Review results, revisit what needs attention and keep your next session tied to one specific certification objective.
Practise DB-DEP with RevizoNo. Revizo is an independent iPhone app for certification practice. Refer to the provider's official resources for current exam policies and registration.
Use the exam code to select the matching certification in Revizo, then build short, focused sessions around the areas you want to review.
No. Revizo provides original practice questions for certification study. Use the provider's official objectives, documentation and policies as the source of truth for your preparation.
Use the current Databricks objectives, documentation and registration guidance as your source of truth. Revizo is designed to support focused practice, not replace the provider's official materials.
Check the official Databricks exam page for the latest objectives, registration details and policies.